Research · Working with AI agents
When AI agents talk, how do you know anyone is listening?
The internal mailbox is built. The next job is proving that each handoff reaches the right agent.
AI tools helped draft and edit this article. I commissioned the project; coding agents carried out the implementation and testing described.
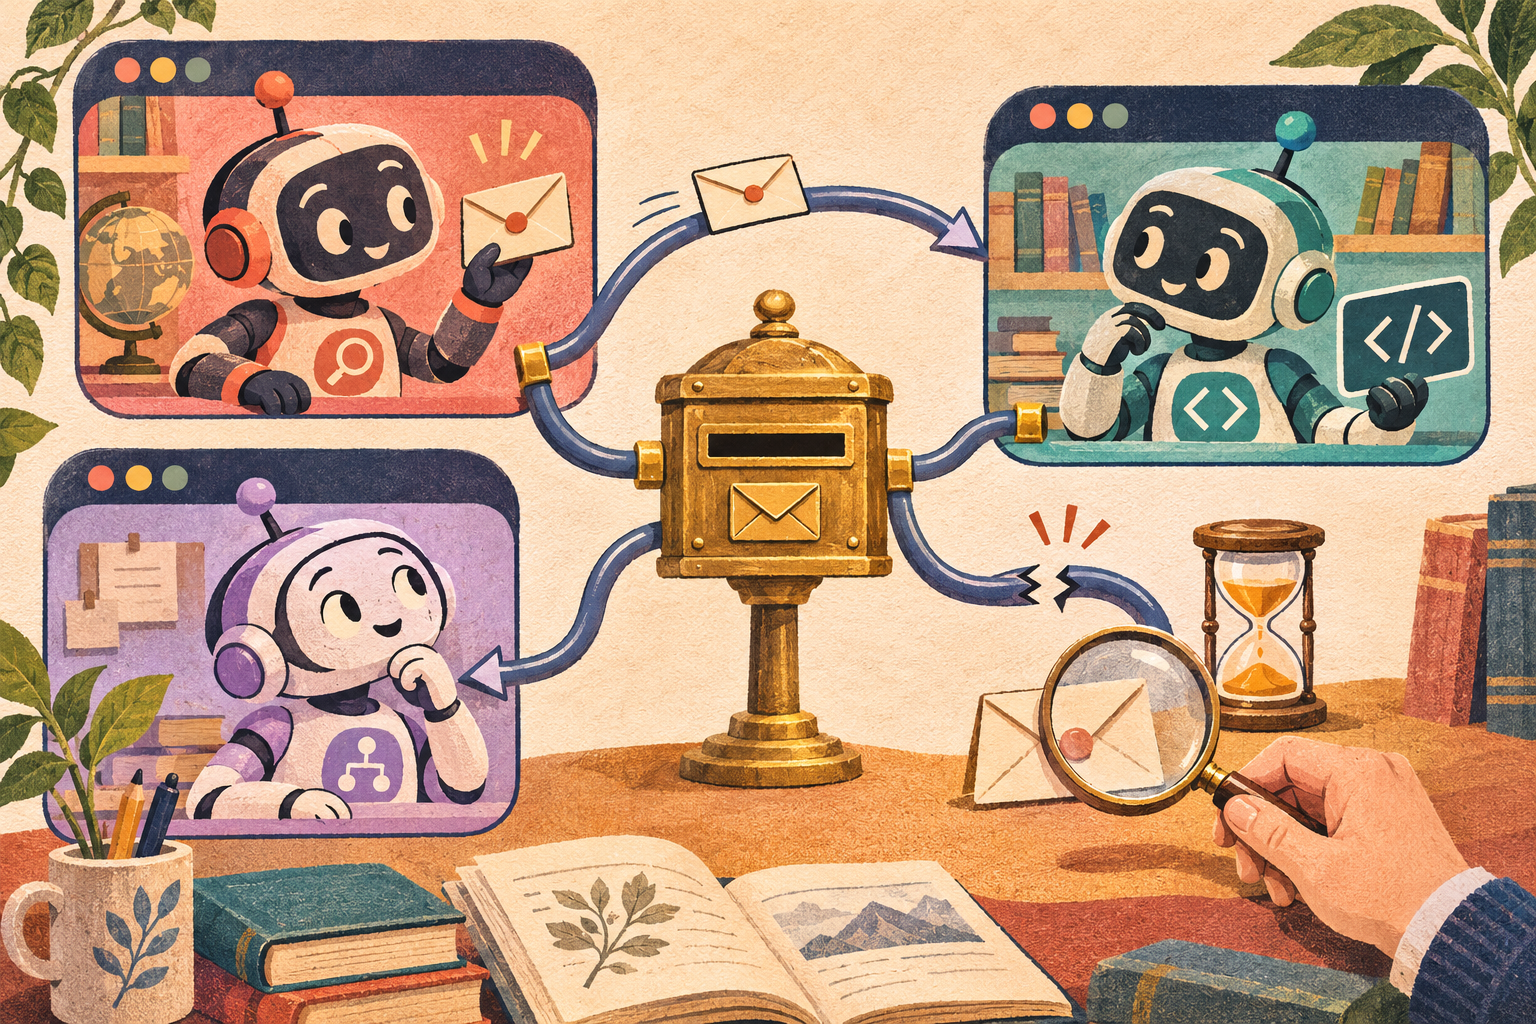
I wanted Grok Bot to pass research work to my coding agents without me relaying every message. We now have an internal mailbox that stores addressed requests and replies. Agents on connected routes can read the relevant message instead of inheriting another agent’s entire conversation.
When the Codex coordinator investigated Grok Bot’s unanswered question, it found that the message had reached Fable’s cloud mailbox. What had not happened was the wake-up that would bring it to Fable’s attention. Storing the message and getting an agent to act on it were two different jobs.
I sighed. Other checks had been done, but the most obvious one was missing: had the message actually brought the request to the agent’s attention?
Who does what
The same working environment brings together Claude, Codex, Grok, Gemini Carbon, Kimi and DeepSeek. The examples in this article involve Claude or Codex acting as coordinator agents: assigning work, inspecting replies and running checks. That is one role within the wider group. I set the direction and decide what can be published; the technical findings below come from the agents’ reports.
Grok Bot is one part of the wider working environment described in the first article. cmux organises the separate agent sessions on my Mac. T3 Code provides a conversation and project-file interface to some of the coding agents, including those on the rented server. The directory and messaging code must connect the agents behind those views.
How the mailbox works
The mailbox stores the request and gives it an ID. The sender passes a short pointer to the intended agent; the agent reads that particular entry when it needs the detail. A reply can refer back to the same request. The registry records who the agent is, its recorded task and where it should be reachable; delivery code gets the pointer into the agent’s conversation.
An address such as agent:report-builder identifies the worker rather than a temporary window number. It is an illustrative address here. The registry and delivery code have to agree about the worker’s current destination; the failed route check showed why that cannot be taken for granted.
The directory provides recorded tasks as well as identities, so an agent can look for the colleague responsible for a job. That information needs to be current. Many requests still go through a coordinator to keep ownership clear, even when two workers could discuss the detail directly.
Keeping task context outside the chat
The mailbox is also a way to control how much context gets passed around. The full brief stays in the stored message or the files it references. A worker can read the exact message and supporting material it needs, without loading all of the coordinator’s earlier conversation.
Where the alternative would be copying tens of thousands of tokens of discussion into another agent’s prompt, a focused brief can avoid much of that input. The actual saving depends on what the receiving agent needs to read; we have not measured a consistent per-turn saving.
This does not erase the history already inside an active session. Reading a message still uses tokens. The benefit is selective access to shared task records, so unrelated conversation need not travel with every handoff.
What does “received” mean?
A message appearing in a conversation does not prove that the model has processed it. A reply referring to the request can provide evidence of consumption, but still does not establish that the agent understood it correctly or did useful work.
These are distinctions I want the system to preserve. The diagram does not mean every transport currently exposes a reliable receipt for every stage. If evidence is missing, the status should stay unknown.
Here is an illustrative receipt, not an exported record or the live API schema:
{
  "message_id": "example-001",
  "to": "agent:report-builder",
  "state": "queued",
  "conversation_delivered_at": null,
  "model_consumption_evidence": null,
  "result_checked_at": null
}
This records a queued request. It cannot support a claim that work has started.
A timeout is a reason to investigate
A timeout alone cannot tell the coordinator whether a message failed to arrive or whether confirmation failed on the way back. Resending without checking could give a worker the same task twice.
For an uncertain send, the coordinator needs to retain the attempt record and look for evidence at the exact intended destination. An exact message match would establish its presence there; a relevant response would establish more. Neither alone verifies the requested repair.
That is an acceptance rule for the setup. A message reaching the mailbox does not establish that it woke the intended agent or that the work was done.
A green check can test the wrong thing
The agents’ release-probe work provided another example. Their review reported that a release check could show green even when a configured job pointed to a script missing from the release.
The coding agent added a check for that entrypoint. An independent coordinator then tested the candidate using automated tests and a temporary release-build exercise: removing the configured script produced a failure. Unsupported launch shapes were reported as uncertain rather than green.
Those checks established behaviour in the test environment. They did not establish a successful installation or reliable automatic waking. That needed a separate operational check.
The worker’s report needs checking too
A shortened repair request from that work shows the division of responsibility:
The release probe reports green when its configured script is missing. Write a failing test, fix the check, and return the revision and test results. Do not install anything or resend queued messages.
The worker proposes the repair. The coordinator checks the revision and reproduces the relevant test. For report work, it also needs to inspect the actual rendered file; a test result is not a substitute for looking at the page.
I want the resulting update to tell me what is ready, what was checked and what remains unresolved. I don’t need every acknowledgement repeated into my conversation. I do need to decide whether a report is ready to publish.
The handoff brought in another agent
The next exchange gave me a more concrete example. I asked the Codex coordinator to investigate the unanswered Grok Bot question with the Carbon agent. Carbon reported a gap between storing a message in the cloud mailbox and putting it onto the route that wakes the destination agent. It prepared an isolated repair.
The coordinator reran Carbon’s tests and tried another case: what if the message was accepted, but the confirmation timed out? The proposed code could retry and publish it twice. The coordinator sent that finding back. Carbon changed the handling to retain the duplicate-prevention claim and report uncertainty. The coordinator’s independent check then produced one message across two attempts; the extracted code suite finished with 86 tests passing and three skipped.
The coordinator passed the reviewed candidate to Fable, who already owned the messaging migration. I hadn’t included Fable in the original request. Fable accepted responsibility for the integration, preserved the candidate and stopped before installation because the existing publication and deployment holds had not cleared. That was a useful distinction: the repair had been reviewed, but the live system had not changed.
There are limits to what this exchange proves. The Codex coordinator manually submitted the initial mailbox pointer to the idle Carbon session; it was not evidence that automatic waking worked on every route. The caller wiring and a live delivery test were still outstanding. Retaining a claim after a timeout avoids an immediate duplicate, but can leave an uncertain attempt needing investigation. I found the exchange useful because those limits travelled with the work, rather than disappearing when it reached the next agent.
What we are finishing
The mailboxes let the agents exchange work. Grok Bot’s question was stored, and the later exchange carried a repair through review to the agent responsible for integration. The missing step was reliably waking the right agent when a message arrived.
That is the next part of this project, and a subject for a follow-up: what should wake an agent, how do we know it noticed, and what happens if its session has restarted? For now, I can distinguish a message waiting in a mailbox from work someone is actually doing. I still decide whether the result is ready to use.